Knowledge base
What our engineers learn in the lab, written down
Every platform we propose is first built on our own OpenShift cluster in Dhaka: Kafka and change data capture, PostgreSQL across two sites, Redis and Data Grid, NVIDIA AI Enterprise and the RAG blueprints. The engineers who do that work write up what they find, and this is where it lives.
It is here so you can check our claims before you sign anything, train your own team on the same material, and see how a platform is actually built, not just how it is sold.
Labs
Step-by-step guides, built and tested on our cluster, from installing an operator to a working pipeline.
Articles
Reference explainers on the platforms and vendors we work with, reviewed and updated as the market moves.
Slideshows
Decks from our briefings you can present or share, slide by slide, with a PDF to download.
Published labs
The newest labs first. Each one names the versions it was tested on.
- Microservices
Microservices with .NET on OpenShift
Build three .NET 10 microservices that talk over HTTP and Kafka, each with its own PostgreSQL database, then containerise them on Red Hat UBI images and deploy them to OpenShift with health probes, autoscaling and OpenTelemetry.
Updated
- DevOps and CI/CD
DevOps and CI/CD: the complete guide
What DevOps is, how CI/CD pipelines work stage by stage, GitOps and deployment strategies, security in the pipeline, and how to build it all with open-source tools and on Red Hat OpenShift.
Updated
- NVIDIA AI Enterprise
NVIDIA AI Blueprints: from reference workflow to production
What NVIDIA AI Blueprints are and what is inside one, the catalog and the blueprints that matter for banks, government and defence, and how to run, customise and take a blueprint to production on OpenShift, with the RAG Blueprint as the worked example.
Updated
- AI applications
RAG: retrieval-augmented generation explained
What RAG is, how its two pipelines work, the building blocks and the decisions behind each, where it goes wrong, and the stack we use for it in our OpenShift lab.
Updated
- AI applications
Agentic AI: how AI agents work
What makes an AI system an agent, the reason-act-observe loop, tools and MCP, memory and planning, common design patterns, where agents fail, and how to run them safely on OpenShift.
Updated
- AI applications
Building a production chatbot, end to end
The architecture of an enterprise AI chatbot: every component from sign-in to model serving, what happens to one message, conversation memory, streaming, capacity, security, evaluation and deployment on OpenShift.
Updated
Articles
Explainers on the platforms and vendors we work with. Each one lists its sources and the date it was last checked.
- Reviewed
Dell AI Data Platform explained
What Dell's AI Data Platform is, its storage engines and data engines, what shipped and what is on the roadmap, how it connects to OpenShift and RAG, and the questions to ask before putting it in a proposal.
- Reviewed
Do classic data pipelines still matter in the AI era?
Why batch jobs, regulatory returns and reconciliation pipelines are more important, not less, now that institutions want AI; what the big data acquisitions of 2025 and 2026 say; and how the pipeline's shape is changing.
- Reviewed
HPE's unified data layer explained
How HPE answers the AI data platform question with three products, the Alletra Storage MP X10000, Data Fabric Software and AI Essentials in Private Cloud AI, what shipped in 2026, and how it compares with Dell's platform.
- Reviewed
Red Hat AI Enterprise explained
What Red Hat AI Enterprise is, which products it brings together, what it does and does not do with data, how it pairs with NVIDIA as the Red Hat AI Factory, and where it fits for an institution in Bangladesh.
- Reviewed
The enterprise AI stack, layer by layer
The eight layers of a production AI stack above and below the data platform, the products that are popular in each, which ones can run air-gapped, and where our labs and services cover them.
Slideshows
Decks from our briefings, with a link for every slide and the PDF to download.
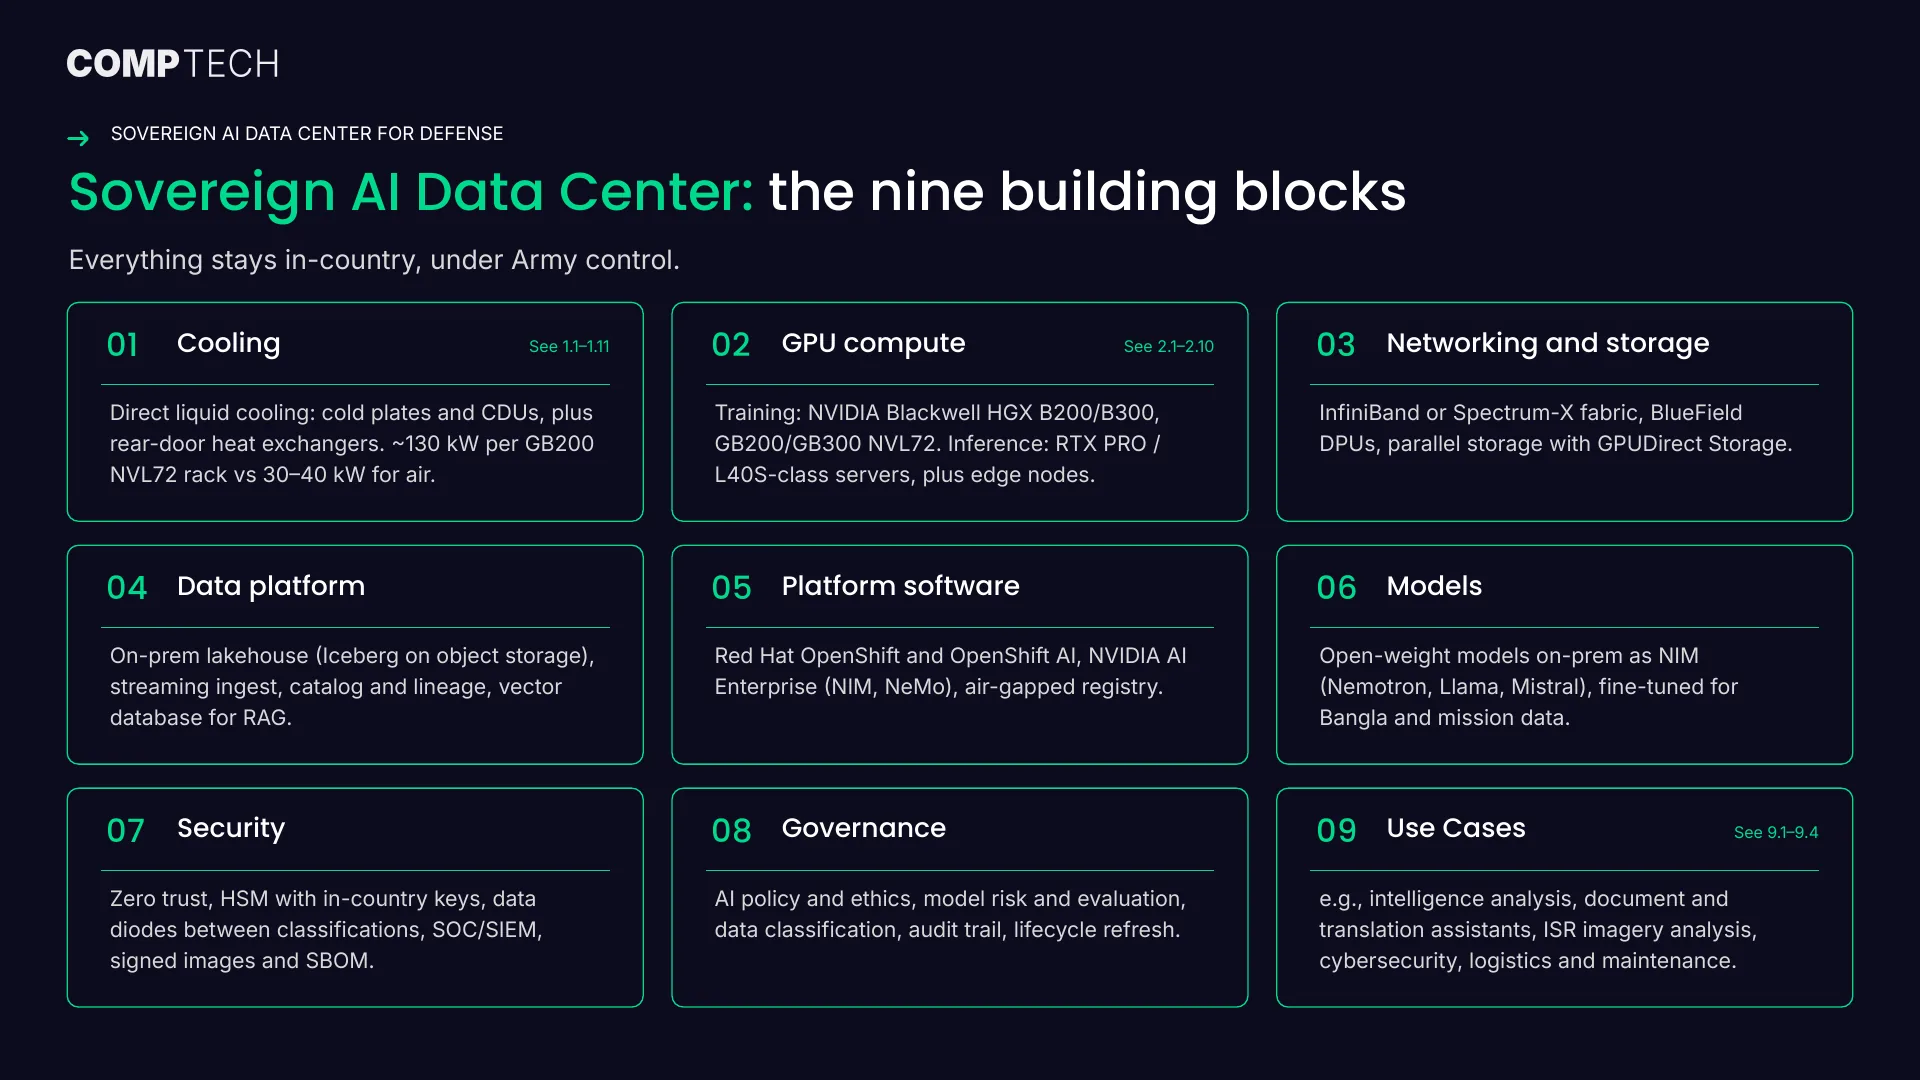
From the blog
Longer reads on AI infrastructure, data platforms and data centres.
AI data platforms and the enterprise AI stack: a map for 2026
Every infrastructure vendor now sells an AI data platform. What Dell, HPE, NetApp, VAST, Databricks, Snowflake, Oracle, IBM and Cloudera actually offer, why classic data pipelines still matter, the other layers of the enterprise AI stack, and what runs on premises for banks and government in Bangladesh.
Liquid cooling vs. air cooling: why the next data centre will be plumbed, not fanned
AI racks now draw 100 kW and more, well past what air can carry. A practical guide to direct-to-chip and immersion cooling, the energy and water they save, the OEMs that supply them, and what it means for a data centre in Bangladesh.
How to build a RAG system: the pipeline, the stacks, and where NVIDIA's blueprints fit
Retrieval-augmented generation is how an organisation's own documents become answers. A practical guide to the ingestion and query pipeline, the open-source, NVIDIA and cloud stacks you can build it from, what the NVIDIA AI Blueprint for RAG actually contains, and how to do it well with Bangla documents.
Want this built for you?
Everything here is the groundwork for the platforms we deliver. Tell us what you are planning and we will point you to the right lab, or the right team.
Talk to CompTech